Direct or delegated
Keep short actions in the foreground. Hand multi-step work to a background executor through an explicit task contract.
 Qwen-Audio-3.1-Realtime
Technical overview
A voice that reasons. An assistant that acts.
Bringing spoken intelligence, real-world execution, and natural
interaction into one continuous conversation.

Model capabilities and system design in one view. Persistent tasks and memory are runtime extensions; matched 3.1 duplex measurements are not yet reported.
Audio MultiChallenge
+5.09 percentage points vs. 3.0τ²-Bench Audio
+3.59 percentage points vs. 3.014-language QA overall
+6.40 percentage points vs. 3.0EchoMind
+0.33 score points vs. 3.0Selected results from the technical report. Explore each dimension
with exact values, metric definitions, and comparison scope.
GPT-Realtime-2 uses low effort unless stated otherwise. Results reflect the report's evaluation settings, not controlled training ablations or statistical significance. A missing result is not treated as zero. S2T results evaluate speech input with text output, not synthesized speech quality.
A persistent voice-agent runtime keeps the conversation responsive while longer tasks move forward—with explicit state, bounded memory, and results delivered at the right moment.
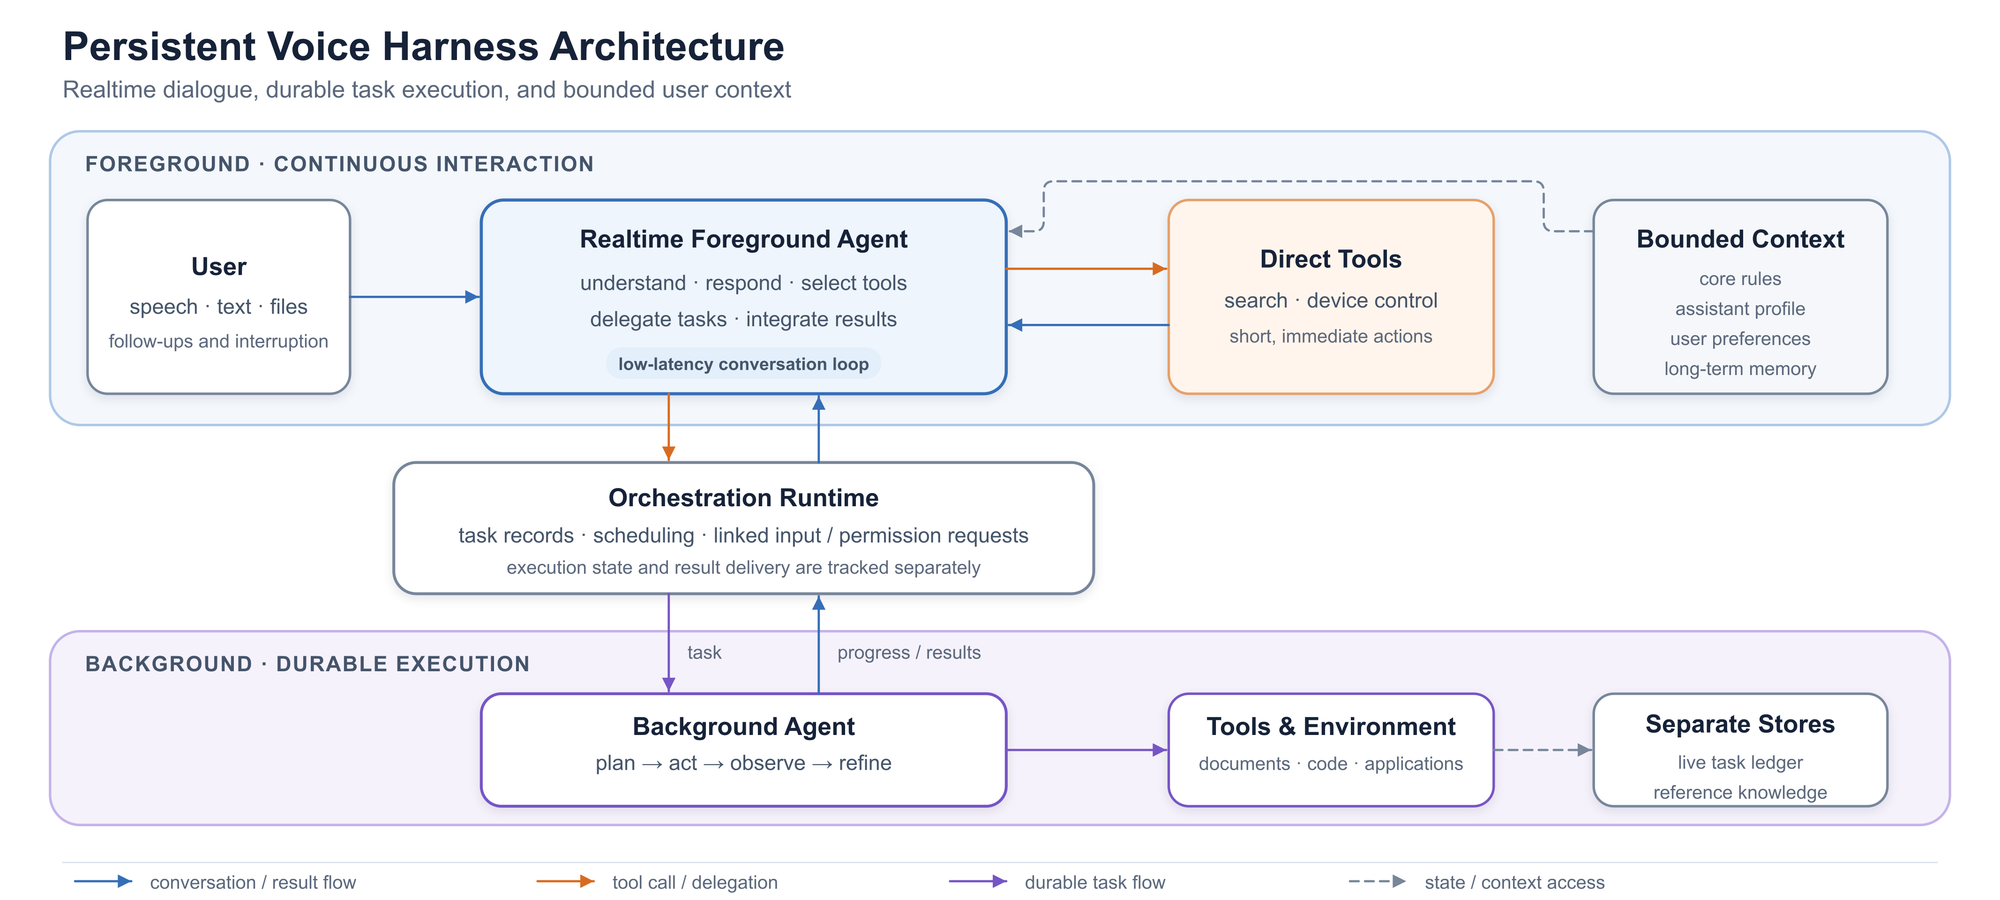
Keep short actions in the foreground. Hand multi-step work to a background executor through an explicit task contract.
Track acceptance, execution, completion, and delivery separately. Follow-up inputs remain linked to the original task.
Separate user preferences, long-term memory, reference knowledge, and live task state. Current instructions take precedence.
Qwen-Audio-3.1-Realtime frames realtime interaction as Think, Act, and Speak & Coordinate — reasoning over evolving requests, executing verifiable actions, and governing how, when, and whether to speak — with evaluation mirroring each layer. Against 3.0, the reported setting gains 5.09 percentage points on Audio MultiChallenge, 6.4 points on the 14-language Big Bench Audio extension, and 3.6 points on τ²-Bench Audio, while multi-turn attack success falls by 54.50 points in Chinese and 40.00 points in English.
Explore the voice agent